Dalilk Academy, 2026In development
B-roll Library
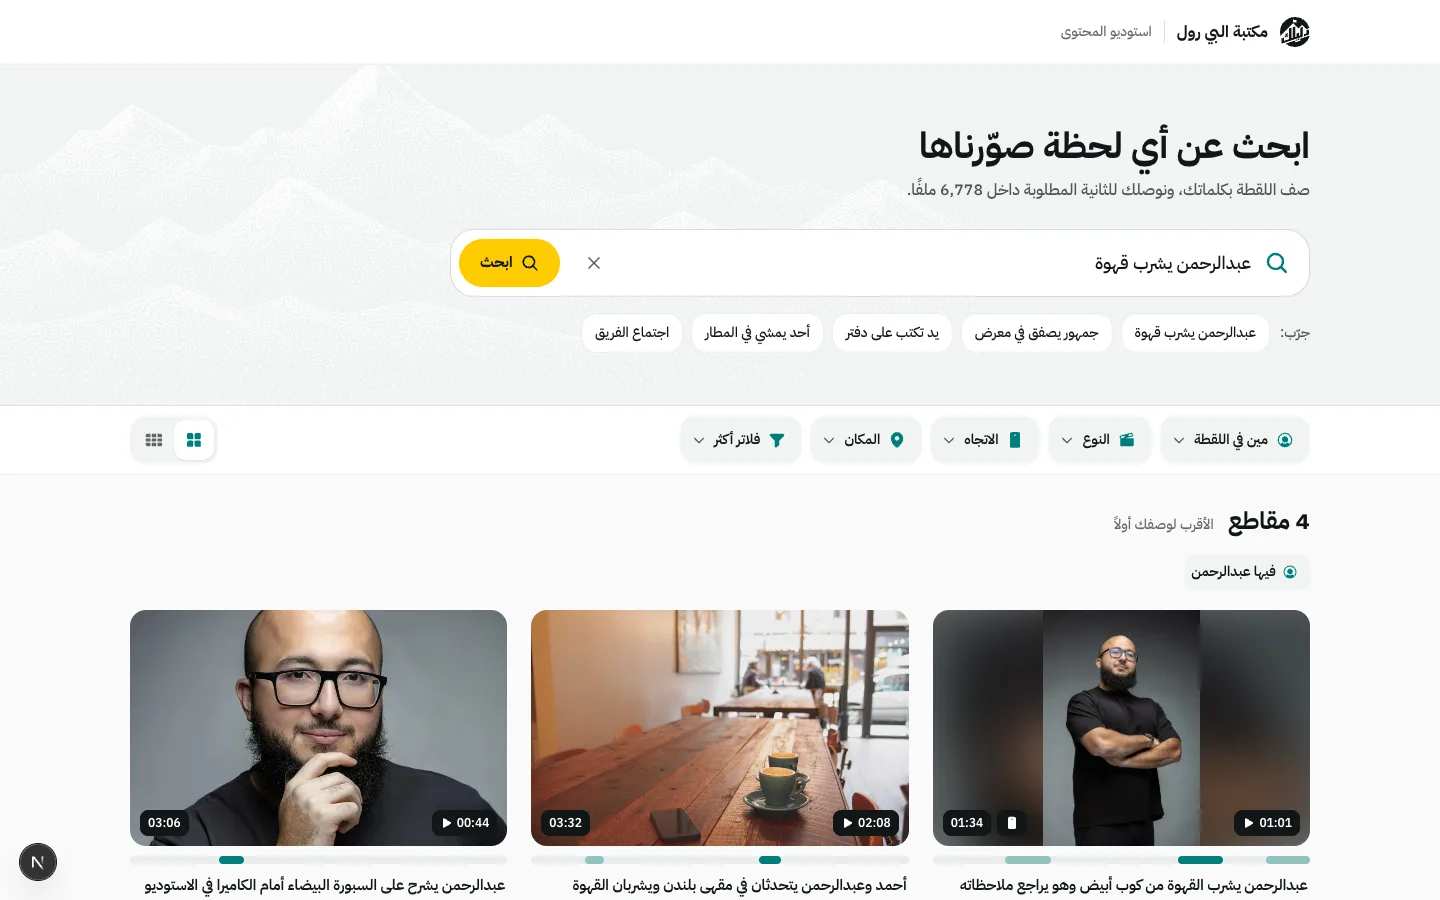
Type what you need in Arabic or English, get the exact second it happens.
At a glance
- clips catalogued
- 6,778
- languages: Arabic and English
- 2
- API cost per clip
- 0
- Role
- Product, design, full build
- Stack
- Next.js, Postgres + pgvector, Whisper
Result
The whole library, 6,778 clips, is catalogued with Arabic and English summaries and searchable by description. Moment-level indexing (scenes, faces, speech, vectors) passed a pilot of 62 source files and is now rolling out across the library. Every model runs locally, so indexing costs nothing per clip.
The problem
I’m one of the editors who needed this. Our B-roll lived in thousands of Drive files, tagged by hand in Notion at the file level. Finding a five-second shot of one person doing one thing meant scrubbing through footage. That’s time taken from the actual edit.
What I built
- A worker on our Mac Studio pulls footage from Drive and splits it into scenes.
- Each scene gets a speech transcript, recognized team faces, a visual caption, and Arabic and English vector embeddings.
- Hybrid search mixes Arabic full-text with semantic vectors, so slang and synonyms still match.
- The web app plays from the matched second, loops it, and copies a clip reference editors can paste.
- It's also exposed as an MCP server, so AI agents can search footage too.
Stack
- Next.js
- Postgres + pgvector
- Whisper
- Qwen2.5-VL
- BGE-M3
- Cloudflare R2
- MCP
Want something like this for your team?
Get in touch